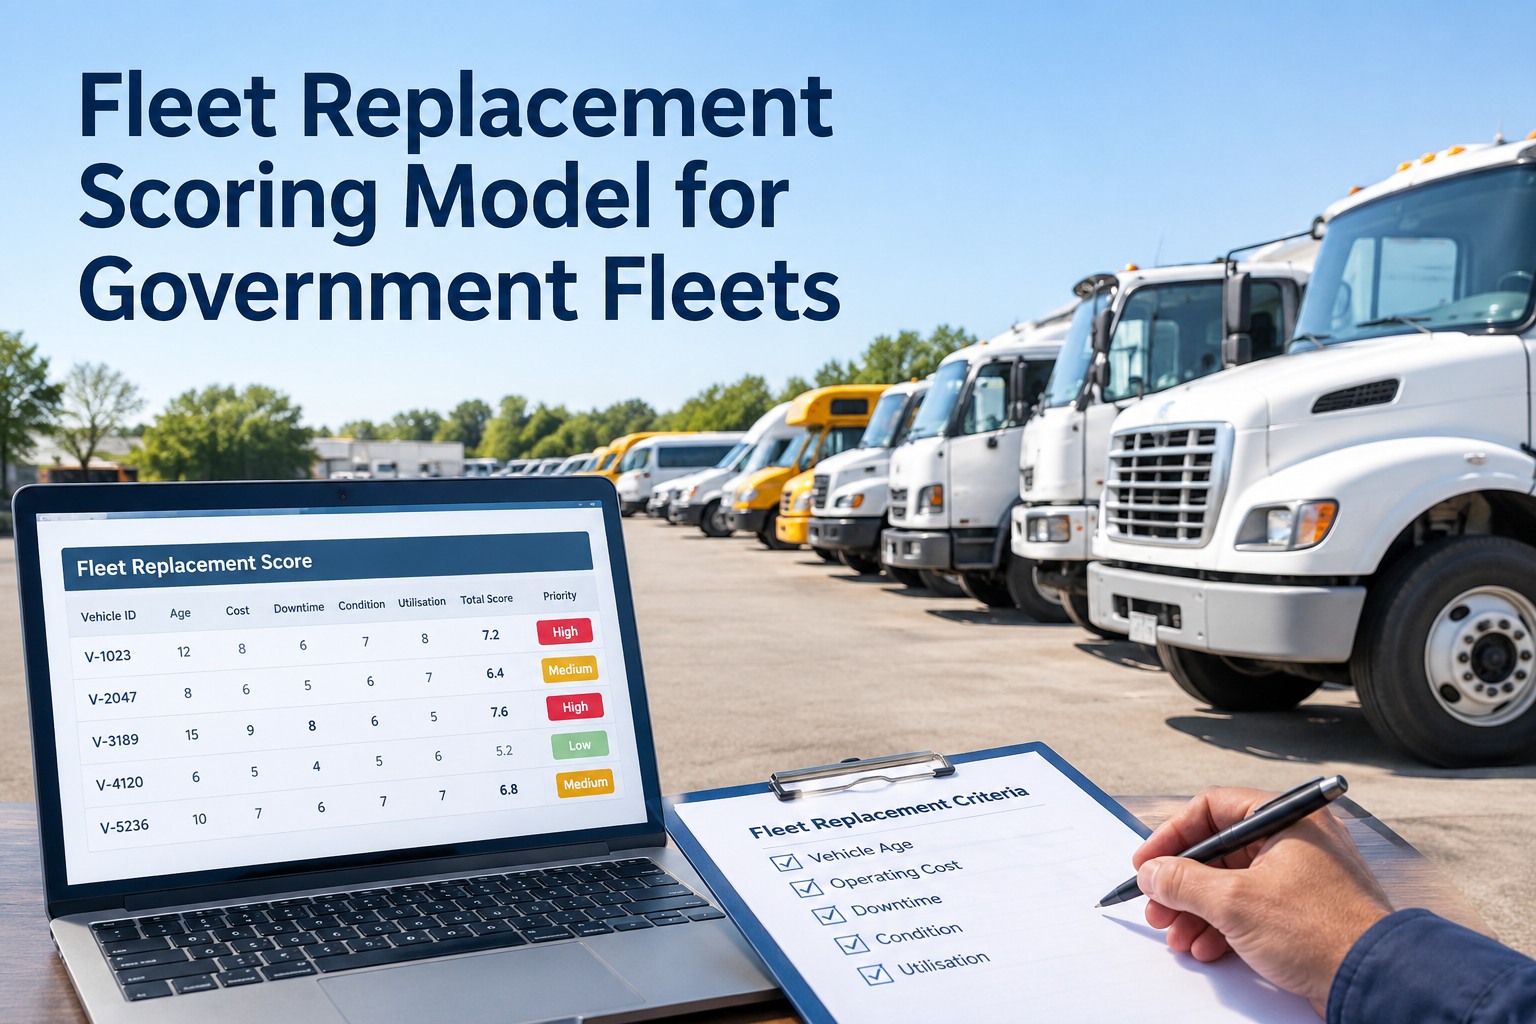
Every year the replacement list is longer than the budget, and someone has to decide which trucks get funded — the moment that rests on which department shouts loudest, you've lost the council. A fleet replacement scoring model replaces that argument with a number: every vehicle ranked on the same weighted criteria, so capital goes first to the units that are genuinely costliest, least reliable, or least safe. See the data a replacement score runs on
Stop Arguing Over Which Truck to Replace. Score Them All the Same Way.
Pick a vehicle. Watch its criteria compose into one replacement score — the same model applied to every asset, so the ranking defends itself.
A scoring model only works if it's built to be trusted — by the departments it ranks and the council it's presented to. Below are the dimensions to score, the weighting decision that has to be made as policy, the data the whole thing depends on, and how transparency and an exception process keep it defensible year after year.
The dimensions a replacement score should measure
A single factor lies. Age alone retires a lightly-used unit with years left; cost alone misses the truck that's cheap to fix but always in the shop. A defensible model blends several dimensions so no one signal dominates — the same approach behind established models like the USDA Forest Service's RScore.
Age & accumulated meter
Years in service plus mileage or operating hours against a class-specific benchmark — actual use, not just calendar age.
Lifetime maintenance cost
Total repair and maintenance spend, often as a ratio to acquisition cost — the 60–70% line where replacement turns economical.
Repair frequency & downtime
Repeat shop visits and days out of service — a unit that's constantly unavailable disrupts more than one expensive one-off repair.
Condition, safety & utilisation
Documented inspection scores, safety findings, and how hard the unit is actually worked — the professional judgement the numbers can't capture alone.
Each dimension answers a different question, and together they produce a ranking that survives scrutiny because no department can dismiss it as "just age" or "just one bad month." The mix is what makes it fair. Book a demo to see these dimensions scored per vehicle.
The weighting decision: set it as policy, once
Here's where most scoring models quietly break. How much each dimension counts — the weighting — is a genuine policy choice, and it has to be agreed and documented up front, then applied to every vehicle identically. The moment weightings get tweaked to move one favoured asset up or down, the whole model loses the neutrality that made it defensible.
Weighting as policy
Agreed once with stakeholders, documented, and applied to every asset the same way. A public-safety fleet might weight downtime heavily; a light-admin fleet, cost. Either is fine — if it's the rule for everyone.
Weighting per asset
Adjusting the weights to get a specific truck the score you wanted. It feels harmless, but it's exactly what a challenged department will point to — and it turns an objective model back into a judgement call.
The discipline is simple to state and hard to hold: you can debate the weights all you like before they're set, but once they're policy, the model runs and the ranking is what it is. That constraint is the source of its authority. Book a demo to apply one weighting across the whole fleet.
The prerequisite everyone skips: complete data
A scoring model inherits the quality of its inputs, and this is where good intentions die. If maintenance cost is half-captured, downtime is estimated from memory, and utilisation lives in three spreadsheets, the score is precise-looking nonsense — and the first department to lose out will find the gap and use it to discredit the whole exercise.
Incomplete records don't just weaken the score — they hand every ranked-low department a reason to reject it. Complete, per-vehicle cost, downtime, and utilisation history isn't a nice-to-have for a scoring model; it's the thing that makes the output believable at all.
This is the real reason a scoring model and a maintenance system go together: the ranking is only as trustworthy as the work-order, downtime, and inspection data feeding it. Get the data captured automatically and the score stops being arguable. Book a demo to see complete per-vehicle history behind each score.
What keeps the model fair year after year
A scoring model isn't a one-time spreadsheet — it's a governance process. Three things keep it honest over time and stop it drifting back into the politics it was meant to replace.
Transparency
Every department can see why its asset received its score — the dimensions, the data, the weighting. A score you can explain is a score people accept, even when they don't like it.
A documented exception process
Real operational needs — a specialised unit, a mission-critical role — get a defined, documented exception path, not a quiet weighting change. The rule bends on the record, not in secret.
Annual re-scoring
Condition, cost, and utilisation change every year, so the model re-runs every year. A truck that was "monitor" last cycle can be "replace now" this one — the ranking stays current.
Together these turn a scoring model from a number into an institution — something the fleet office, the departments, and the council all understand and trust the same way. That shared trust is what actually gets budgets approved. Start free and re-score your fleet on current data each year.
Taking the score to council
The payoff for all the discipline arrives in the budget meeting. When a finance director asks why the replacement request is what it is, a documented scoring methodology plus asset-level evidence answers every line — not with opinion, but with the same model applied to every vehicle, and the data behind each score.
Fleet managers who walk in with this don't defend their list; they present it. The ranked scorecard shows why each unit sits where it does, the exception log shows where judgement was applied and recorded, and the exportable report gives finance something to keep. Requests survive that scrutiny because there's nothing to challenge that the data doesn't already answer. It's the difference between "trust me, these are the worst trucks" and "here is the model, here are the scores, here is the evidence." Book a demo to see an exportable replacement scorecard for council.
The fleet replacement scoring model checklist
Work through this to stand up a scoring model that holds up in front of departments and council alike. Use this replacement scoring checklist online free, with age, cost, downtime, and condition tracked against each vehicle automatically.
Choose your scoring dimensions
Age and meter, maintenance cost, downtime and repair frequency, condition, safety, and utilisation.Set weightings as policy
Agree and document how much each dimension counts — once, with stakeholders, for every asset.Verify the data is complete
Confirm cost, downtime, and utilisation records are captured per vehicle before you trust the output.Make each score explainable
Every department can see the dimensions and data behind its asset's score — no black box.Define the exception process
A documented path for genuine operational needs — on the record, not a hidden weighting tweak.Re-score annually & export for council
Re-run the model each budget cycle and export the ranked scorecard with asset-level evidence.
From a fleet director who took a scorecard to council
My replacement request jumped from $780K to over a million, and the finance director wanted to know why. In the old days that meeting would have been me insisting the trucks were bad and her not believing me. This time I pulled up every candidate's scorecard right there — age, cost ratio, downtime, reliability, condition, per vehicle.
Two candidates actually dropped off once we looked at the scores together, and three moved up because the downtime data showed they were bigger risks than I'd flagged. We landed at $940K and council approved it without challenging a single line. That doesn't happen on opinion — it happens because every number in the room came from the same model and the same data.
Frequently asked questions
What is a fleet replacement scoring model?
It's a structured method for ranking vehicles by replacement priority using a weighted blend of criteria — typically age and accumulated meter, lifetime maintenance cost, repair frequency and downtime, utilisation, and documented condition or safety findings. Instead of replacing on a single rule like age, each vehicle gets a composite score, and limited capital goes first to the highest-scoring units. Government fleets use it to turn a subjective, contested replacement list into a consistent, defensible ranking that holds up in front of departments and council.
What criteria should be in a replacement scoring model?
Blend several so no single signal dominates: age and accumulated mileage or operating hours against a class benchmark, lifetime maintenance cost (often as a ratio to acquisition cost), repair frequency and days of downtime, utilisation, and documented condition and safety findings. Established models like the USDA Forest Service's RScore combine maintenance-cost points, age points, and meter points for exactly this reason. Downtime deserves its own weighting because a vehicle that's constantly unavailable disrupts more operationally than one unit with a single expensive repair.
How should the weightings be decided?
As documented policy, agreed once with stakeholders and applied to every vehicle identically. How much each dimension counts is a legitimate choice — a public-safety fleet might weight downtime heavily, a light-admin fleet cost — and any consistent choice is defensible. What breaks the model is adjusting weightings to move a specific favoured asset up or down; that turns an objective ranking back into a judgement call and gives any challenged department grounds to reject it. Debate the weights before they're set, then hold them fixed.
Why does data quality matter so much for scoring?
Because a score inherits the quality of its inputs. If maintenance cost is only half-captured, downtime is estimated from memory, and utilisation is scattered across spreadsheets, the score looks precise but isn't trustworthy — and the first department ranked low will find the gap and use it to discredit the whole model. Complete, per-vehicle cost, downtime, and utilisation history is the prerequisite that makes the output believable. That's why a scoring model works best on top of a maintenance system that captures the data automatically.
How does a scoring model help with budget approval?
It replaces opinion with evidence in the room. When a finance director or council questions a request, a documented scoring methodology plus asset-level data answers every line: the same model applied to every vehicle, the score each received, and the cost, downtime, and condition history behind it. Fleets that present a ranked scorecard rather than a wish list see requests approved with fewer challenges, because there's nothing to dispute that the data doesn't already explain. It converts "trust me" into "here is the model and the evidence."
Turn your replacement list into a scorecard council can't argue with
HVI captures the age, utilisation, maintenance cost, downtime, and condition data a replacement scoring model runs on — per vehicle, automatically — and exports the ranked result for capital planning. So you build the model once, apply one weighting to every asset, re-score each year, and walk into the budget meeting with a ranking that defends itself line by line.
No credit card · Age, cost, downtime & condition per vehicle · Exportable ranked scorecard